Retail attribution models assign credit for a sale to the marketing touchpoints that led to it. The most defensible approach combines multi-touch or model-driven attribution as a directional signal with incrementality experiments as ground truth, backed by disciplined data hygiene before you trust any output. The rest of this guide breaks down how each model works, where retail data breaks attribution logic, and how to build a validation routine that catches false wins.
TL;DR:
- Linking ad exposure to specific SKUs is challenging due to product variants, and offline channel contributions are often undercounted if only digital events are tracked.
- Data quality issues, such as misaligned timestamps and inconsistent identifiers, are among the biggest hurdles before building reliable attribution models.
- Simpler models like position-based or linear attribution are suitable for early-stage measurement, but more complex, experiment-backed approaches improve accuracy for mature teams.
- Ground truth validation through experiments like geo-lift tests and holdouts is essential because attribution models only show presence, not causation.
- Retail attribution reports require ongoing calibration and documentation to prevent false insights and ensure the results remain trustworthy over time.
Table of Contents
- What retail attribution actually measures
- Common attribution models and how they assign credit
- Data and infrastructure checklist before you model anything
- How to choose the right attribution approach for your team
- Validating attribution with experiments and hybrid calibration
- An implementation roadmap from audit to governance
- What agency work on retail attribution actually teaches you
- How we help retail teams build attribution that holds up
- FAQ
- Sources
What retail attribution actually measures
Retail attribution assigns marketing credit across touchpoints, channels, and SKUs, tracking how a shopper moved from exposure to purchase, whether that purchase happened online or at a register. It answers a narrow question: given the data we captured, which touchpoints were present before this sale. It does not answer whether the sale would have happened anyway.
That distinction separates attribution from incrementality. Attribution describes what happened; incrementality measures what was caused. A shopper who saw a sponsored product ad, then searched the brand name, then bought in-store, generates multiple attribution claims across channels, but only one of those touchpoints may have actually changed their behavior.
Retail adds specific complications general marketing attribution does not face. SKU-level matching has to reconcile product variants, bundles, and private-label overlaps. Halo effects, where advertising one product lifts sales of an adjacent item on the shelf, rarely show up in standard click-to-sale tracking. Fulfillment method (buy online pick up in store, ship-to-home, in-store only) changes which systems log the conversion event at all. If your attribution model only in gests digital conversion events, it will systematically undercount channels that primarily drive offline visits, like local search, in-store signage, or retail media placements, even when those channels are working.
Common attribution models and how they assign credit
Attribution models differ in how they split credit across the touchpoints a shopper encounters before buying. Each comes with a logic that sounds reasonable in isolation and breaks down under specific retail conditions.
First-touch gives 100% of the credit to the first interaction a shopper had with your brand. It is simple to implement and useful for understanding which channels build awareness, but it ignores everything that happened between discovery and purchase, so it overvalues upper-funnel channels and undervalues the touchpoints that actually closed the sale.
Last-touch does the opposite, crediting the final interaction before conversion. It is the default in most retail media dashboards because it is easy to compute from click logs, but it systematically overweights bottom-funnel channels like branded search and retargeting, which often intercept shoppers who were already going to buy.
Multi-touch models split credit across several touchpoints using different weighting logic:
- Linear distributes credit evenly across every touchpoint in the path, treating awareness and conversion channels as equally important.
- Time-decay weights recent touchpoints more heavily, assuming interactions closer to purchase carry more influence.
- Position-based (U-shaped) assigns most of the credit to the first and last touchpoints, with the remainder split across the middle.
- W-shaped extends that logic to credit a third milestone, typically the point a shopper converts from anonymous to identified.
- Custom-weighted models let a team assign weights based on internal judgment or historical performance, trading standardization for flexibility.
Data-driven or machine-learning attribution replaces fixed weighting rules with statistical models trained on historical conversion paths, estimating each touchpoint’s actual contribution rather than applying a preset formula. Amazon’s published MTA methodology, for example, combines machine learning models with randomized controlled trials to allocate credit, then uses the experimental results to calibrate the model’s outputs. That combination matters because a model trained purely on observational data can mistake correlation for causation. A shopper exposed to retargeting right before purchase may have simply been close to buying already, and the model has no way to know that unless an experiment tells it so.
Data and infrastructure checklist before you model anything
Attribution outputs are only as trustworthy as the inputs feeding them, and in retail, most of the real work happens before a single model runs.
- Collect the essential inputs: ad event logs, point-of-sale and SKU-level sales data, the promotional calendar, and a current product catalog with consistent identifiers.
- Align timestamps across systems, since ad platforms, retailer dashboards, and POS systems often log events in different time zones or with different latency.
- Stitch identity where possible, linking loyalty IDs, hashed emails, or device IDs to the same shopper across channels, and build an explicit rule for handling shoppers who never get identified.
- Deduplicate conversions that multiple platforms are independently claiming, using a consistent order ID or receipt match where available.
- Choose and document a lookback window per category, since a fast-moving consumable and a considered big-ticket purchase do not convert on the same timeline. The IAB/MRC retail media measurement guidelines recommend a 30-day post-view and post-click default, with flexibility to adjust by category and a requirement to disclose whatever window you ultimately use.
Pro Tip: Budget most of your project timeline for data cleaning and mapping, not model selection. Practitioner write-ups consistently point to harmonizing media logs, digital shelf signals, and retail sales as the majority of the effort in any attribution project.
How to choose the right attribution approach for your team
The right model depends less on sophistication and more on whether your data and decision cadence can support it.
Weigh these factors before committing to an approach:
- Data maturity: do you have clean, deduplicated conversion events across every channel you want to measure, or are you still stitching sources together.
- SKU granularity: can you reliably match ad exposure to specific products, or only to broad categories.
- Channel complexity: are you running three channels or fifteen, since complexity multiplies the deduplication burden.
- Budget for experiments: do you have the spend and patience to run geo-lifts or holdouts, or are you working from observational data alone.
- Decision cadence: are you making weekly budget calls that need fast directional signals, or quarterly strategy calls that can wait for a rigorous test.
A simple rule-based model like position-based or linear attribution is acceptable when you are early in building measurement discipline, have limited channel overlap, and need a quick directional read. Move to data-driven attribution or experiments once budget and channel complexity grow enough that a fixed weighting rule starts producing results that contradict common sense.
Before adopting any vendor’s attribution numbers, demand disclosure on:
- The weighting logic or model type used.
- The lookback window applied and whether it varies by category.
- The extrapolation rate for unidentified users, since retailers often model attribution for shoppers they cannot directly track.
Validating attribution with experiments and hybrid calibration
Attribution is not causation, and the only way to know whether a channel actually drove sales is to test it. An attribution model can tell you a touchpoint was present before a purchase; it cannot tell you the purchase wouldn’t have happened without it.
Experiments provide that ground truth. Options include:
- Randomized controlled trials, where you randomly withhold exposure from a control group and compare outcomes, the cleanest design but often the hardest to run at retail scale.
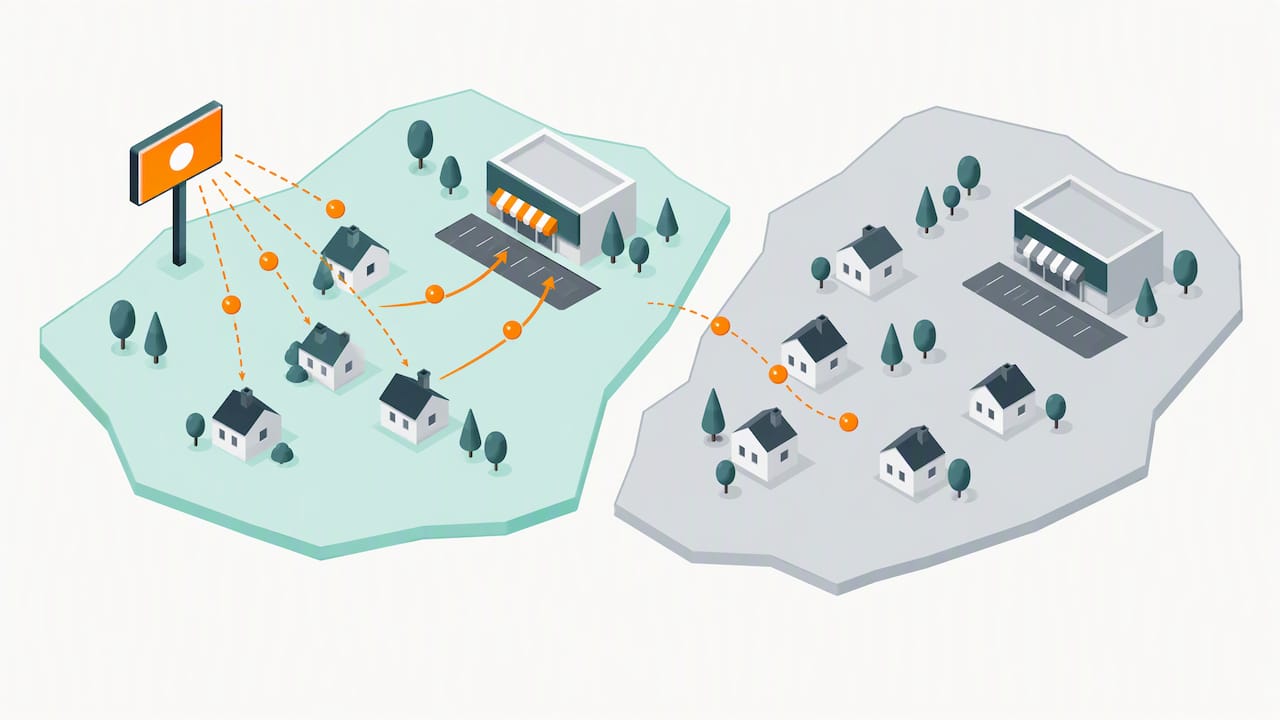
- Geo-lift tests, comparing matched markets with and without a campaign, practical when individual-level randomization is not feasible.
- Holdout tests, withholding a treatment from a subset of eligible shoppers within a single platform.
- Synthetic controls, building a statistical proxy for what a market would have done absent the campaign, useful when a true control group is unavailable.
IAB and IAB Europe’s incremental measurement guidelines stress that a credible counterfactual is the core requirement of any incrementality claim, regardless of which design you choose. Amazon’s own MTA methodology goes a step further, using RCT results to calibrate its machine learning attribution outputs, an approach often called causal calibration, so the model’s directional read stays anchored to a measured reality rather than drifting on correlation alone.
The most common pitfall is control group contamination, where shoppers in your holdout group get exposed anyway through another channel or a retailer’s own promotion. Mitigate it with geo-level separation rather than individual-level holdouts when cross-exposure risk is high, and treat any test running on a tight timeline or during a heavy promotional period with extra skepticism.
Pro Tip: Run small, frequent geo-lift tests rather than one large annual experiment. It is easier to detect seasonality or contamination early when you are cross-checking results every few weeks instead of waiting a full year to find out your design was flawed.
An implementation roadmap from audit to governance
Moving from ad hoc reporting to a defensible attribution practice happens in phases, not all at once.
- Audit your data first. Map every system generating sales or exposure events, identify where timestamps, product IDs, and sales definitions do not match, and fix the deduplication logic before anything else. This phase alone often takes longer than any modeling work that follows.
- Select a baseline model and pilot it. Choose the simplest model that fits your current data maturity, position-based or linear are reasonable starting points, and run it against one well-understood campaign where you already have intuition about the likely result.
- Run a lightweight experiment to calibrate. A single geo-lift or holdout test against your pilot campaign tells you whether the model’s directional read matches a measured causal effect, and by how much it overstates or understates impact.
- Operationalize into dashboards and governance. Document the model’s weighting logic, lookback window, and extrapolation assumptions in a place stakeholders can actually find, and set a recurring cadence, quarterly at minimum, to re-run calibration tests as channels and promotions shift.
Success looks like fewer surprises when the numbers disagree. Teams that document their assumptions upfront can explain a ROAS swing by pointing to a changed lookback window or a known promotion overlap rather than scrambling to justify a number nobody can reconstruct.
Pro Tip: Write the limitations section of your attribution report before you write the results. It forces discipline about what the model can and cannot claim, and it is the section stakeholders trust most once they see you volunteering it.
What agency work on retail attribution actually teaches you
The most common mistake we see is treating a single attribution report as a final verdict instead of a starting hypothesis. Teams that build in a quarterly calibration habit, even a modest geo-lift here and there, catch false wins long before they become budget decisions built on bad data. The second most common mistake is skipping documentation: weights, windows, and extrapolation rates that nobody wrote down become impossible to defend six months later. Our retail marketing assessment work with clients consistently starts by fixing these two gaps before touching a single media plan.
— Derek
How we help retail teams build attribution that holds up
We build attribution practices the same way we build campaigns: strategy first, data integration second, and measurement that actually survives scrutiny. Our Strategy & Management work covers the full arc, from auditing your current data setup to designing the experiments that calibrate your models against reality, so the numbers you report are ones you can defend.
This approach includes mapping sales, SKU, and ad event data into a unified source before modeling, designing geo-lift or holdout experiments adapted to budget and channel mix, and creating dashboards and documentation to support ongoing result validation.
If your current attribution numbers raise more questions than they answer, our marketing assessment is the place to start. Reach out and we will walk through where your data stands today and what a calibrated model would take to build.
FAQ
Can you give an example of how an attribution model works?
A shopper who saw a display ad, later clicked a search ad, and then converted through an email link would have credit distributed across all three under that formula.
What’s the difference between single-source and multi-touch attribution?
Single-source attribution relies on one dataset or platform, typically last-touch data from a single ad network, to assign full credit for a conversion.
What are the main types of attribution models?
The most commonly used categories are first-touch, last-touch, linear, and position-based (U-shaped), with time-decay and custom-weighted models as common variations. Data-driven or machine-learning attribution is a separate, increasingly common category that assigns credit based on statistical modeling rather than a fixed formula.
How do I choose between first-touch and multi-touch attribution?
First-touch works when you specifically want to understand which channels drive initial awareness, since it credits only the first interaction a shopper had with your brand. Multi-touch is the better default for most budget decisions because it reflects that most retail purchases involve more than one touchpoint before conversion.
Why do attribution and incrementality numbers often disagree?
Attribution describes which touchpoints were present before a sale, while incrementality measures whether that sale would have happened anyway without the marketing exposure. A model can show a channel touched 80% of conversions while an experiment shows that channel only caused a small fraction of incremental sales, because presence and causation are different questions.
Sources
Retail attribution breaks in ways that general digital marketing attribution does not, mostly because retail sales data lives across systems that were never designed to talk to each other, as explained in omnichannel marketing unifying customer experience.
Interoperability between retail networks is a persistent problem. A brand running campaigns across several retail media platforms gets separate reports from each, with different identity resolution logic, different lookback windows, and no shared deduplication layer. Summing those reports produces a return on ad spend that can look mathematically impossible.
Gross versus net sales reporting compounds this. Some retailer dashboards report gross sales before returns and cancellations; others report net. Mixing the two when comparing ROAS across retailers or time periods can make a flat campaign look like it is accelerating, or vice versa. NielsenIQ’s analysis of retail media measurement points out that harmonizing product identifiers and sales definitions across retailer dashboards and brand systems is essential, since mismatches commonly explain large ROAS differences that have nothing to do with actual performance.
Digital shelf conditions confound attribution further. Price changes, stockouts, search rank shifts, and review volume all move sales independently of any ad exposure, and most attribution models have no variable to capture them. A campaign that appears to drive a sales lift might simply coincide with a competitor going out of stock.
Treat reported ROAS as a hypothesis, not a verdict. NielsenIQ warns that ROAS and last-touch metrics describe what happened but frequently get used as a stand-in for what was caused, which it calls a category error in retail measurement.
Other common bias sources worth tracking before you trust a report:
- IAB/MRC Retail Media Measurement Guidelines (January 2024)
- Amazon Ads Multi-Touch Attribution (arXiv)